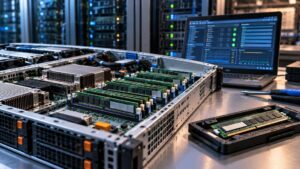
A server reporting a correctable ECC memory error does not automatically need new RAM. The memory system has detected and recovered from a fault, often allowing applications to continue without interruption.
However, repeated errors affecting the same memory module can signal a developing problem. For server administrators, the challenge is knowing when to keep monitoring and when to schedule hardware maintenance.
For a broader discussion of server memory reliability and monitoring, CXL memory infrastructure analysis examines how modern memory architectures create additional operational considerations.
What Correctable ECC Memory Errors Mean
Error-Correcting Code (ECC) memory uses additional information to identify and correct certain memory faults. It is widely used in enterprise servers because memory reliability matters for databases, virtualization, and other critical workloads.
The Linux kernel’s reliability documentation distinguishes corrected errors, where data is successfully recovered, from uncorrected errors that exceed the correction mechanism’s capabilities.
An isolated corrected error does not necessarily indicate permanent hardware damage. Recurring errors, however, deserve attention because some memory faults become more frequent as hardware deteriorates.
ECC is a protective mechanism, not a guarantee that a defective memory module will continue functioning indefinitely.
Warning Signs That Deserve Investigation
The pattern of errors often matters more than an individual notification.
Intel’s server ECC troubleshooting guidance explains that some correctable-error events represent a threshold being reached within a defined period, rather than one individual bit error.
Administrators should investigate when errors repeatedly affect one DIMM, increase in frequency, or appear alongside unexpected restarts and hardware-health alerts.
It is also important to check how a particular server counts these events. A threshold documented for one Intel platform should not automatically become the replacement policy for every server.
How to Diagnose the Problem Before Replacing RAM
Start by preserving the system event logs and identifying the affected DIMM location.
On supported Linux systems, hardware error information may be available through EDAC (Error Detection and Correction) reporting and tools such as rasdaemon. The server’s baseboard management controller may also retain relevant hardware events.
Check the exact server model, firmware version, error history, and physical slot mapping.
Dell’s PowerEdge memory troubleshooting guidance includes reviewing event logs, checking firmware, collecting diagnostics, and reseating memory modules when appropriate.
These steps matter because a reported memory error does not always prove that the DIMM itself is defective.
When Should You Replace Server RAM?
Monitoring is generally reasonable when errors are isolated, the server remains stable, and the manufacturer’s guidance does not require immediate service.
Further diagnosis is appropriate when corrected errors repeatedly affect the same DIMM, become more frequent, or appear alongside degraded hardware status.
Urgent investigation is necessary after an uncorrectable memory error, particularly when accompanied by application failures or system instability. Follow the platform’s recommended recovery and replacement procedure.
There is another important distinction: a faulty DIMM and a faulty motherboard slot can produce similar symptoms.
Intel’s DIMM-versus-slot diagnostic guidance explains how controlled testing can determine whether errors follow a memory module or remain associated with a particular slot.
Such testing should be performed only during an approved maintenance window, with the server safely powered down and manufacturer instructions followed.
Preventing Unexpected Memory-Related Downtime
A useful maintenance policy records corrected-error trends, uncorrectable events, affected DIMM locations, and relevant firmware changes.
It also establishes clear escalation procedures so administrators know when to contact the hardware manufacturer or schedule replacement.
The goal is not to eliminate every corrected-error notification. It is to identify developing hardware problems while there is still time to investigate and maintain the system safely.
A corrected ECC error means memory protection worked. Repeated errors are a reason to investigate whether the underlying hardware is still reliable.