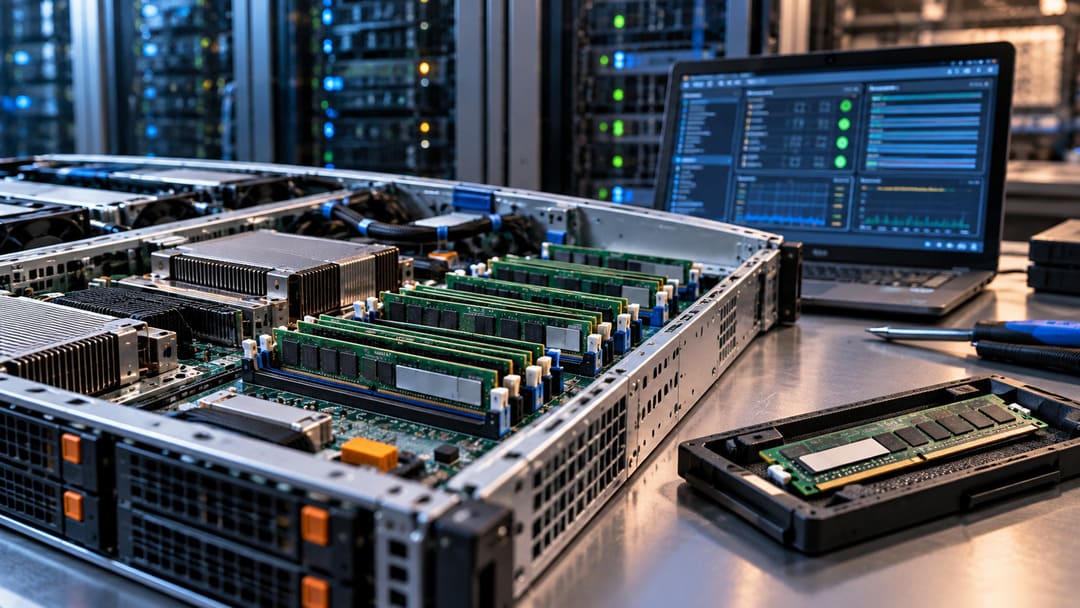
A correctable ECC memory error does not automatically mean a server needs new RAM. Modern servers can detect and correct certain memory faults without interrupting applications. However, repeated errors on the same memory module may indicate a developing hardware problem.
The important distinction is between an isolated corrected event and evidence of continuing deterioration. Replacing every DIMM after one warning can waste money, while ignoring repeated errors can increase the risk of an unexpected failure.
Server management controllers can provide another source of hardware events. HW Server’s coverage of BMC monitoring and management risks explains the separate hardware-management layer that remains accessible even when the operating system is unavailable.
What Correctable ECC Memory Errors Actually Mean
Error-Correcting Code (ECC) memory uses additional information to detect and correct certain data errors. A corrected error means the hardware successfully recovered the affected data.
An uncorrectable error occurs when the protection mechanism cannot fully recover the data. Depending on the affected memory and the server’s recovery capabilities, the result may range from an isolated application failure to a system crash.
The Linux Kernel documentation explains that corrected errors do not necessarily predict future uncorrectable errors. Nevertheless, tracking them can help administrators identify degrading hardware before a serious failure occurs.
The useful warning is not simply that an error happened. It is whether the evidence points to a recurring problem.
Warning Signs That Deserve Investigation
Not every ECC warning describes the same event. Some platform alerts indicate that an error threshold was reached rather than reporting every individual corrected bit error.
Intel distinguishes errors suitable for monitoring from circumstances requiring additional investigation, including repeated events and system instability.
Administrators should pay attention when corrected errors repeatedly affect the same DIMM location, become more frequent, or appear alongside unexpected restarts and other hardware warnings.
Checking only the latest alert can conceal an important pattern. Review the event history, error location, frequency, and any related system-health changes.
On supported Linux systems, tools such as rasdaemon help collect hardware error information.
Red Hat’s hardware-monitoring documentation describes how Error Detection and Correction (EDAC) events can be recorded and summarized. Its examples are from RHEL 7, so commands and availability should be checked against the installed operating system.
When Should You Replace Server RAM?
The decision should reflect the observed pattern, server condition, and manufacturer guidance.
An isolated corrected error on an otherwise stable server may justify continued monitoring rather than immediate replacement. Record the event and check whether it returns.
Repeated errors associated with one DIMM deserve further diagnosis, particularly when their frequency increases or firmware reports degraded memory. A scheduled replacement may be appropriate once the affected component has been identified.
Uncorrectable errors require more urgent assessment. They do not invariably crash a server, but they indicate that normal error correction could not recover the affected data.
There is no universal number of corrected errors that requires replacing every server DIMM. Thresholds and service recommendations differ by platform, firmware, and memory protection features.
Check the Hardware Before Ordering Replacement RAM
A warning identifying one memory location does not always prove that the DIMM itself is defective. Problems may also involve the memory slot, firmware, or memory controller.
Dell’s PowerEdge memory troubleshooting procedure, Dell US includes firmware checks, memory-module reseating, event-log review, and additional diagnostics where necessary.
Before authorizing replacement, confirm the exact server model, reported DIMM location, current firmware, and applicable vendor instructions. Save diagnostic logs before resetting counters or performing disruptive maintenance.
Any physical intervention should follow approved shutdown and servicing procedures. DIMMs must not be removed from a powered server unless its manufacturer explicitly supports that operation.
A corrected error is evidence that memory protection worked. A continuing pattern of errors is evidence worth investigating. Monitoring, identifying the actual fault, and following platform-specific replacement guidance are more reliable than treating every ECC alert as an automatic hardware failure.